PHI Redaction: Protecting Sensitive Health Information for Compliance and Security
PHI redaction detects and masks protected health information across tickets, chat, email, files, and databases; the enforcement layer behind HIPAA de-identification.
· PHI redaction is the detection and masking ofprotected health information — names, MRNs, dates, SSNs, images — inside thetickets, messages, emails, files, and databases where it actually lives.
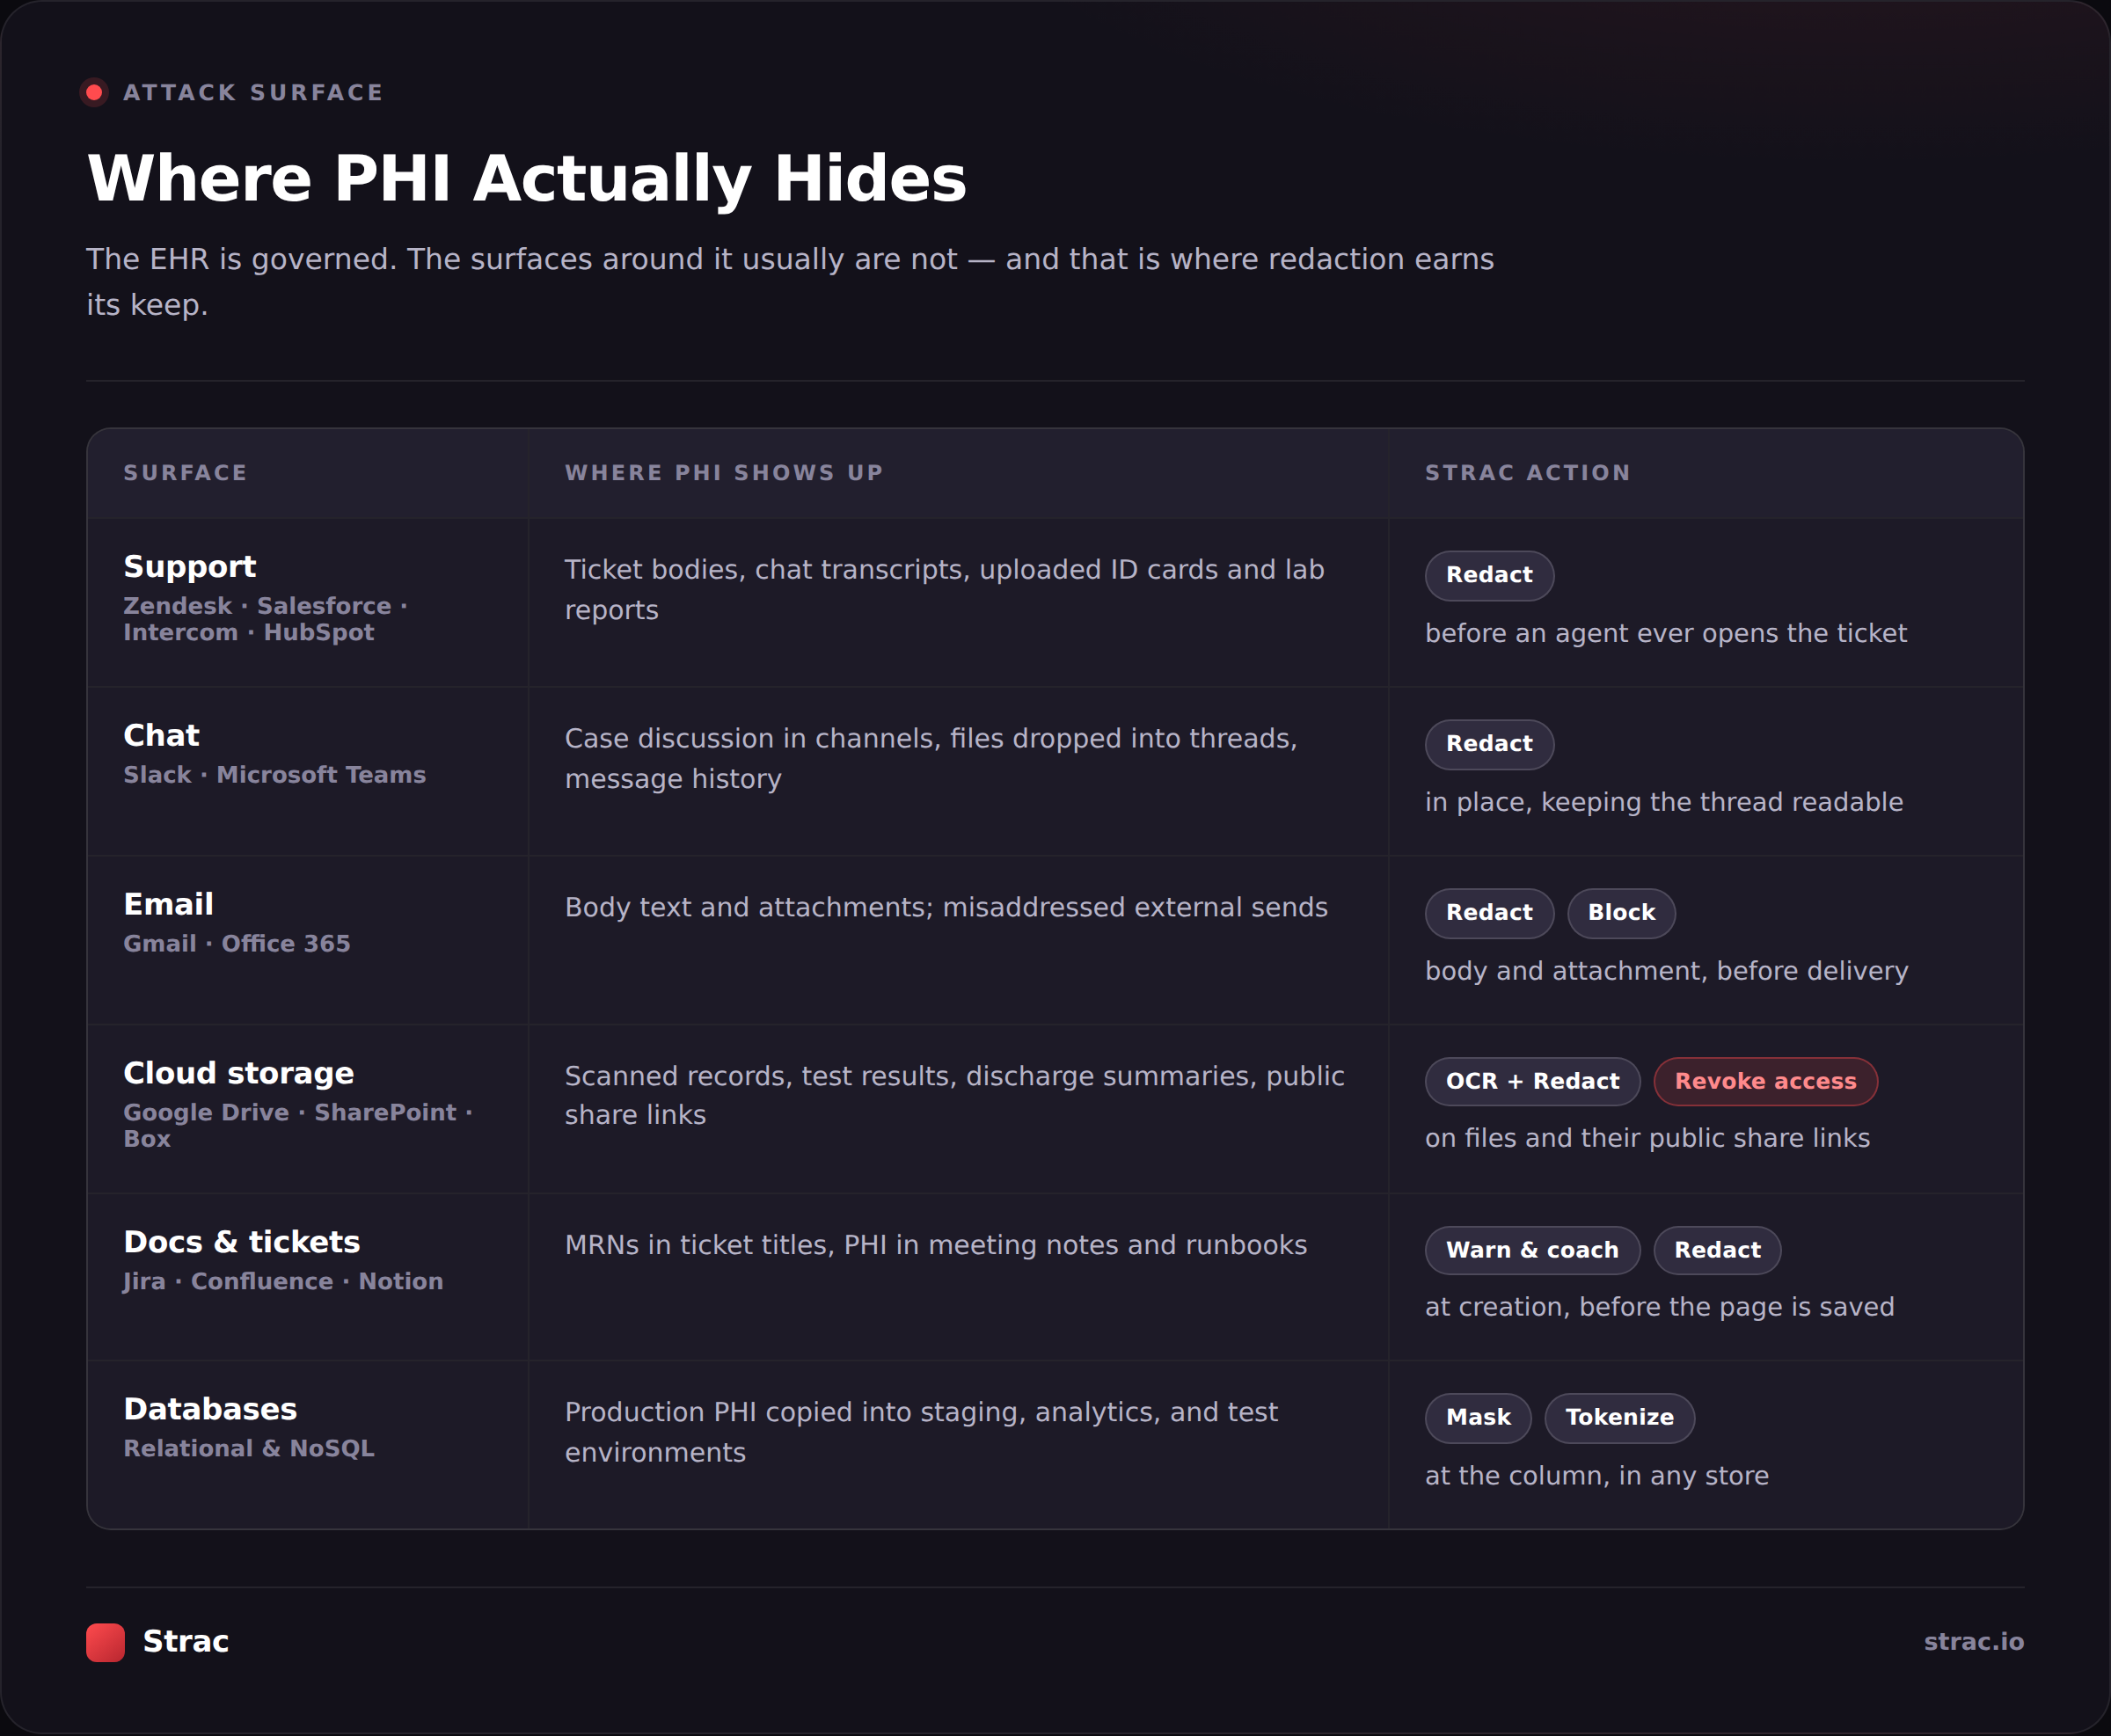
· The risk is not the EHR. It is everythingdownstream: a patient pastes their MRN into a Zendesk ticket, a clinician dropsa lab PDF into Slack, a discharge summary sits in a shared Drive folder with apublic link.
· Legacy DLP misses it because it scans structureddata at rest on a schedule, and PHI arrives unstructured and in motion — insidefree text, attachments, and scanned images.
· Redaction is the enforcement half of HIPAAde-identification: Safe Harbor and Expert Determination tell you what mustgo; redaction, masking, and pseudonymization arehow it goes.
· Strac redacts PHI in real time across SaaS,email, cloud storage, endpoints, and databases — under one classifier and oneaudit trail. Start from the pillar on HIPAAde-identification.
What Is PHI Redaction?
PHI redaction is the process of finding protected health information in a document, message, or record and removing or obscuring it so the content can no longer identify a patient. The redacted artifact stays readable and useful; the identifiers do not survive it.
It applies wherever health data travels: a support ticket, a Slack thread, an email attachment, a scanned PDF in Google Drive, a column in a Postgres table. Redaction is not an archival step performed once before release — it is a control that runs at the moment data moves. That is the difference between data redaction as a policy and redaction as an enforcement point.
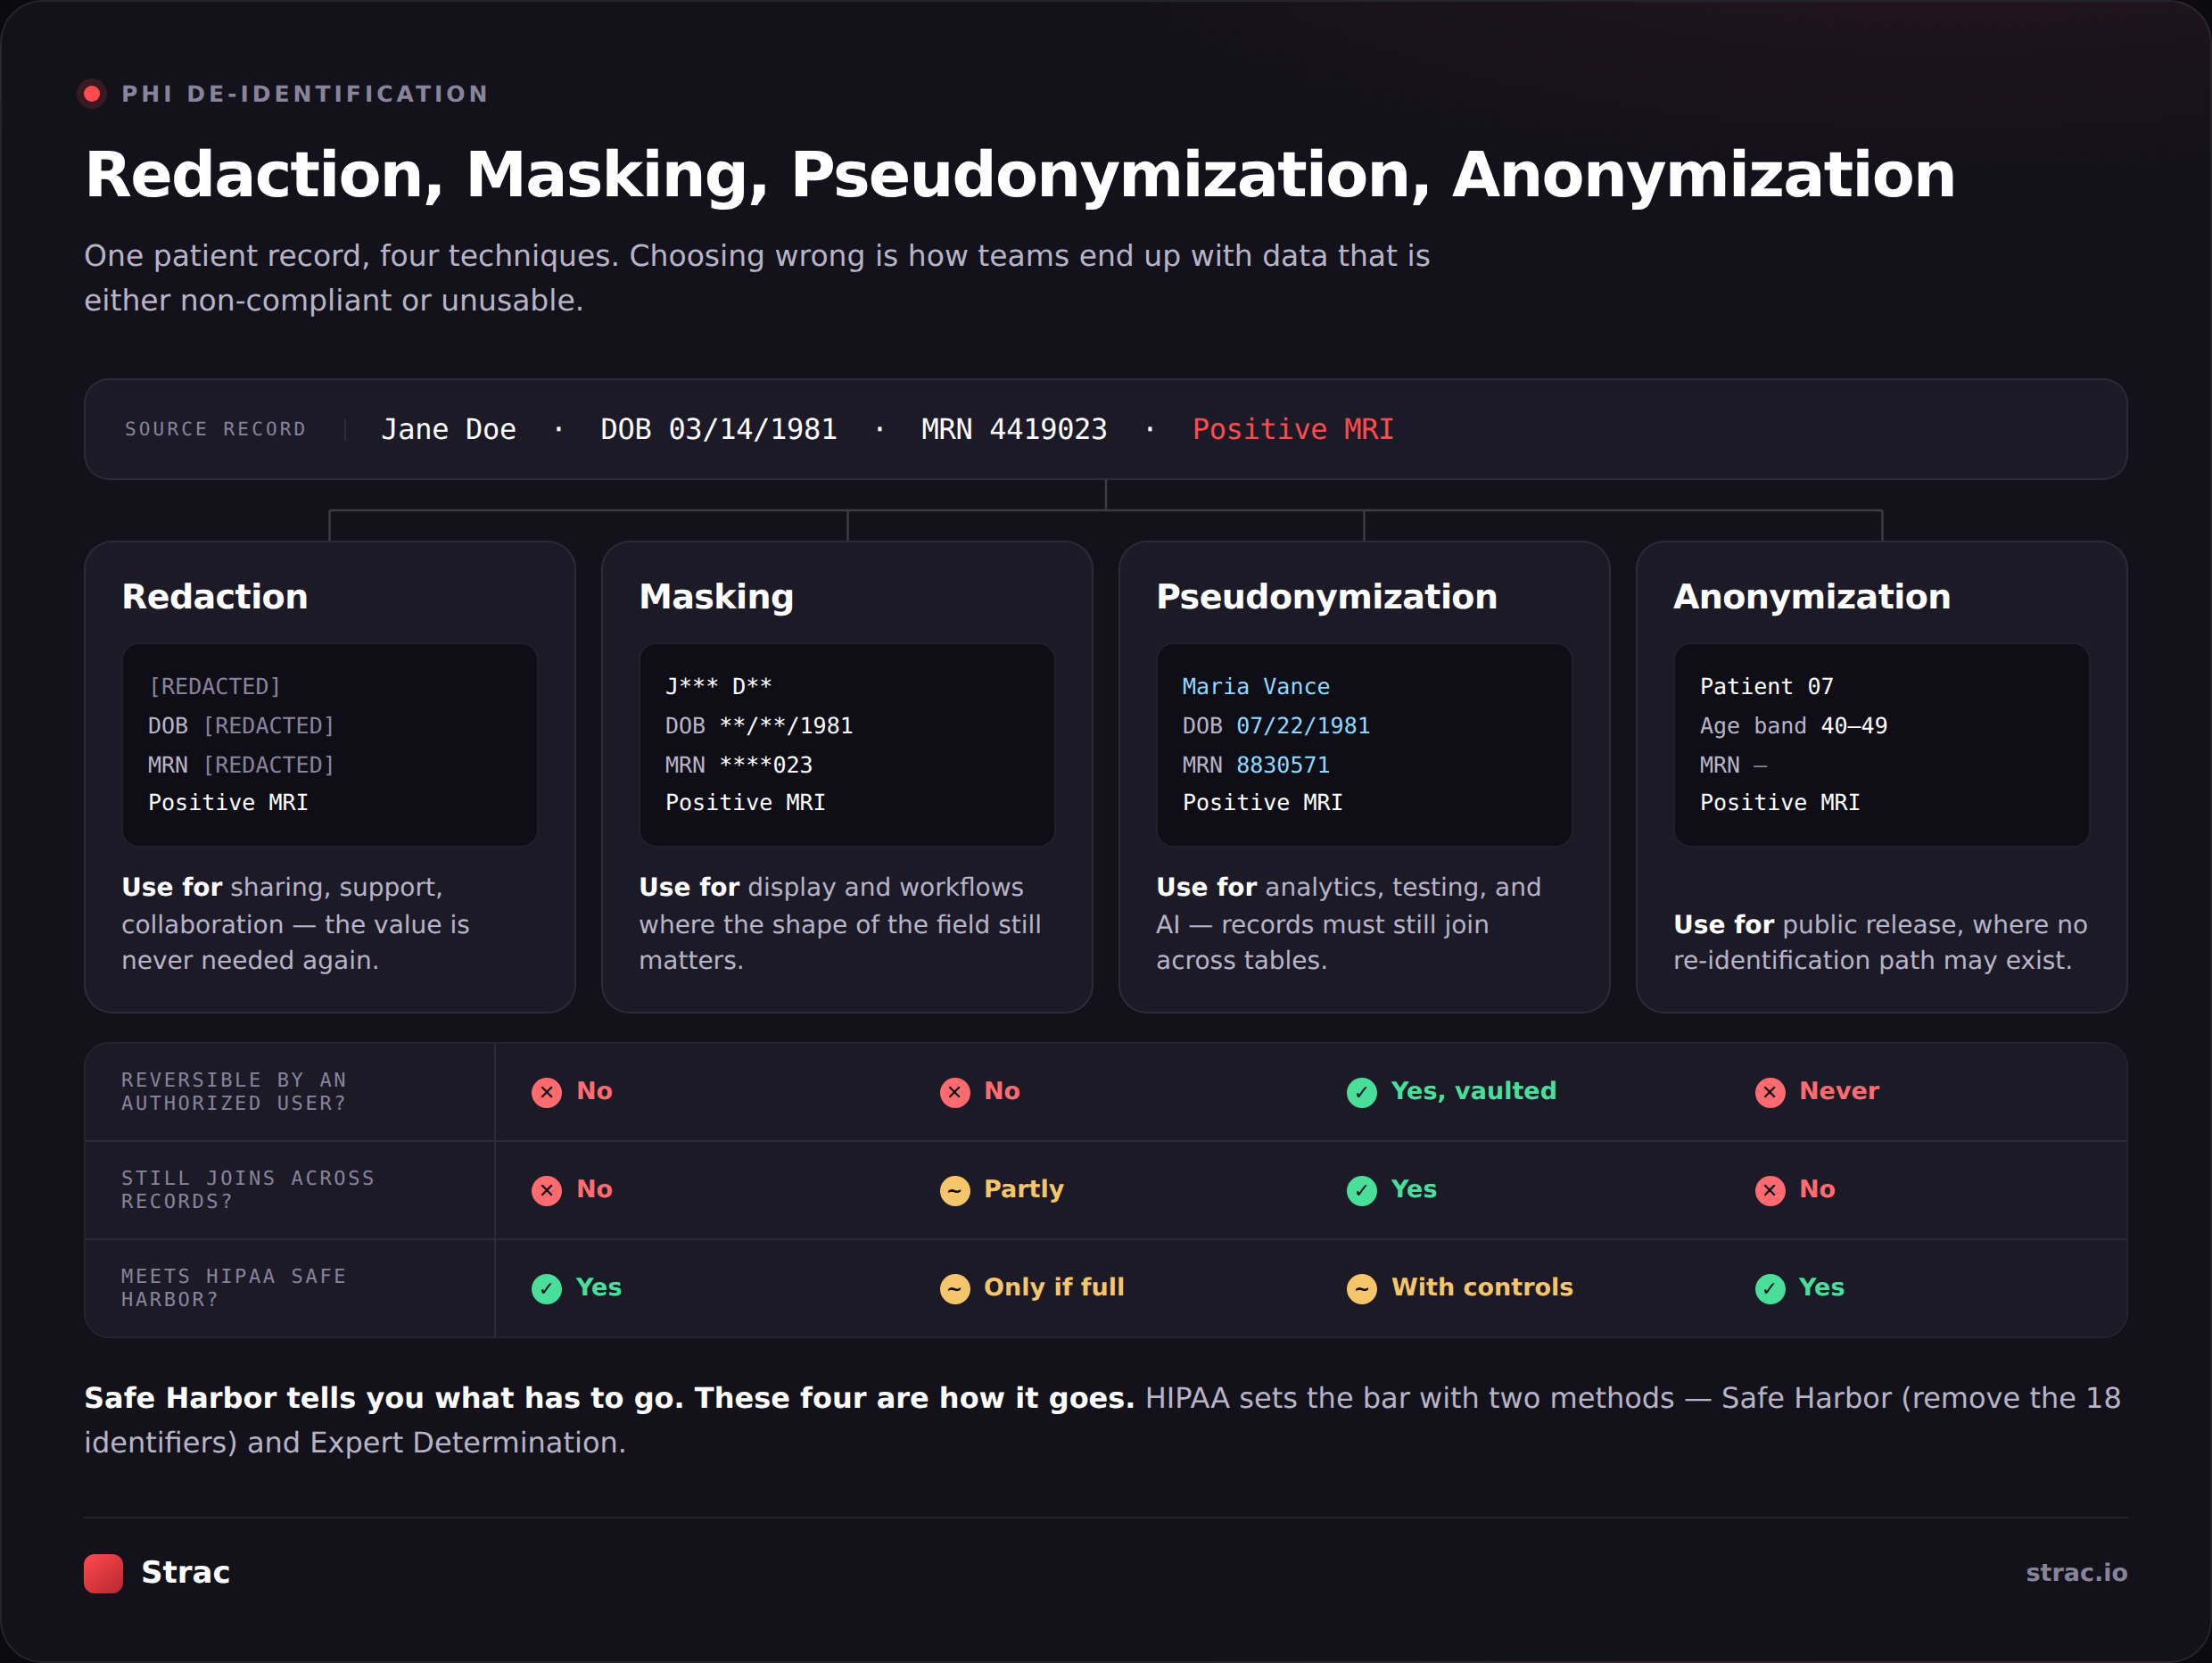
✨ Redaction, Masking, Pseudonymization, Anonymization — the Difference That Matters
These four get used interchangeably and should not. Choosing wrong is how teams end up with data that is either non-compliant or unusable: redact a field your analysts need and you have broken the dataset; mask one they can reverse and you have not de-identified anything.
Two of these deserve a closer look. Pseudonymization is the one to reach for when data must stay usable: it swaps each identifier for a consistent, realistic surrogate, so records still join across tables and a test environment still behaves like production. Anonymization is the opposite trade — irreversible, and appropriate only when no one will ever need the original back.
HIPAA de-identification sets the bar with two methods: Safe Harbor, which removes the 18 HIPAA identifiers, and Expert Determination, which certifies that re-identification risk is very small. Redaction is not a separate standard. It is the mechanism that gets you to one.
Safe Harbor tells you what has to go. Redaction is how it goes.
Traditional DLP was built for structured data at rest: databases, warehouses, file shares, scanned on a schedule. PHI does not wait there. It arrives as free text a patient typed, a PDF a lab emailed, a photo of an insurance card, a screenshot pasted into a ticket. A scanner that checks tables nightly sees none of it.
Three properties make PHI specifically difficult:
It is unstructured. "Mrs. Doe's MRI came back positive" carries PHI with no field name to key on.
It is often an image. Discharge summaries, ID cards, and faxed referrals need OCR before any classifier can read them.
It is contextual. A date is not PHI until it is an admission date attached to a person.
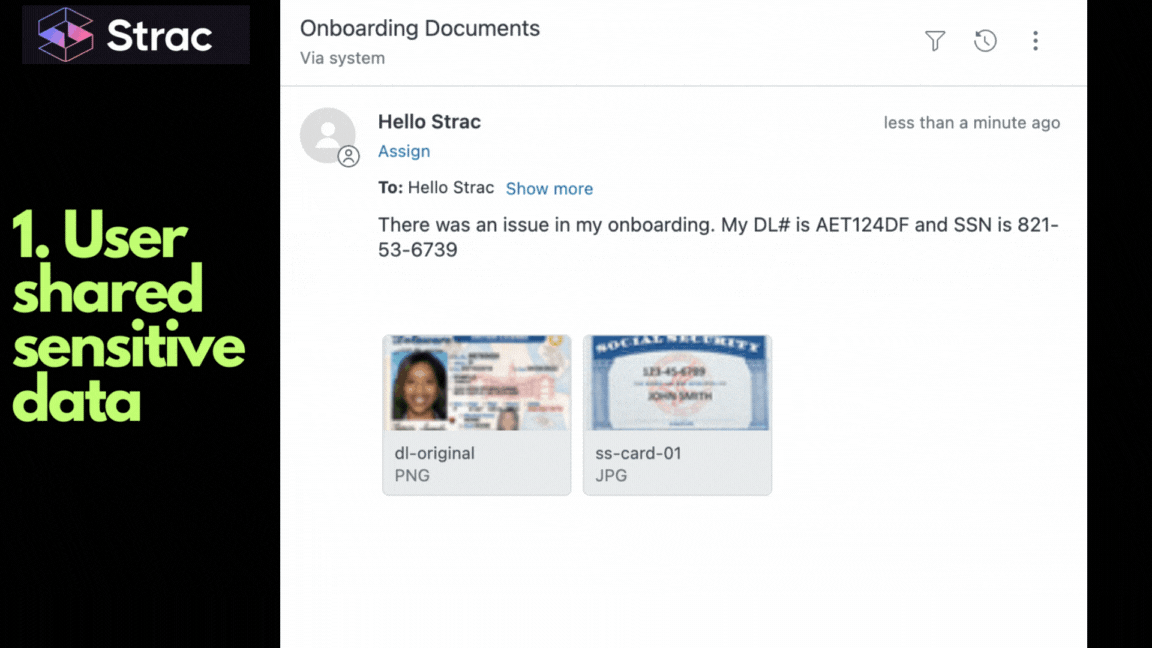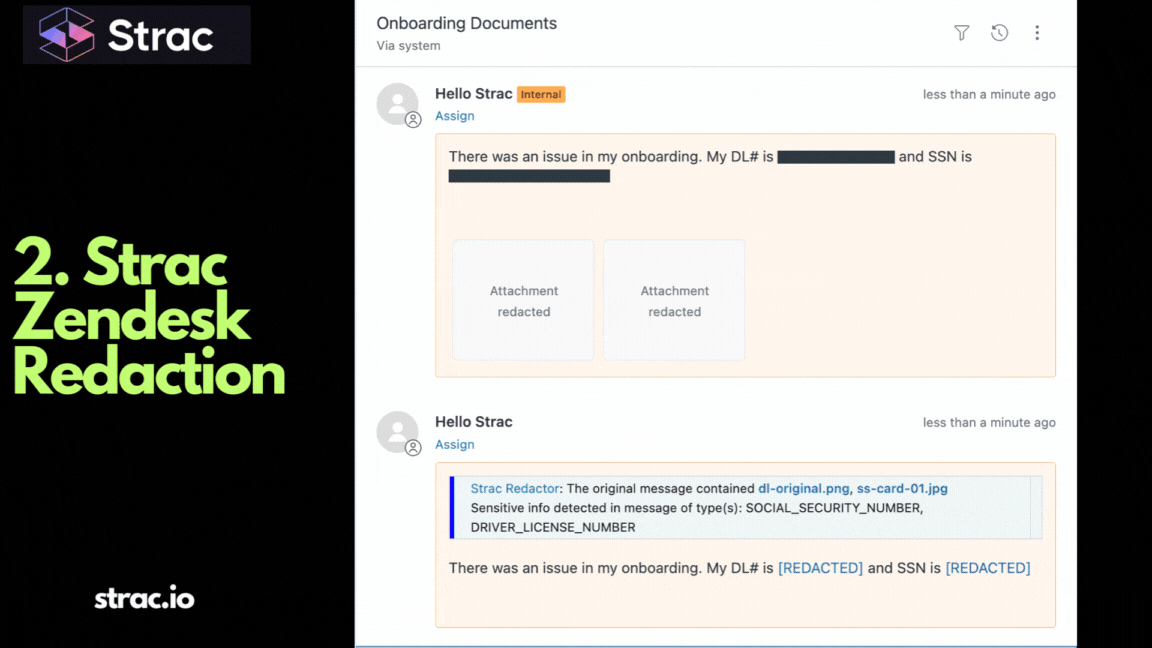
A worked example. A support ticket arrives reading "John Doe's MRI results show a positive diagnosis, MRN 4419023." Before the agent opens it, Strac rewrites it to "Patient [REDACTED]'s MRI results show a positive diagnosis, MRN [REDACTED]." The agent resolves the issue with full context and zero exposure, and the original values stay vaulted for anyone with a clinical reason to see them.
PHI in your Slack channels right now?Most teams find it the week they turn detection on. You can be alerted the moment it lands — without reading a single message.→ Set up automatic PHI alerts in Slack
🎥 How Redaction Works: Detect, Decide, Remediate
Detect. ML and NLP classifiers read text, attachments, and metadata, with OCR for PHI embedded in scans and photos. Detection is contextual, so a nine-digit number is scored as an SSN by what surrounds it, not by its shape alone. The same engine handles audio, where recorded calls carry PHI no text scanner will ever see.
Decide. Policy is set per data type and per surface, not globally. An MRN in an internal Jira ticket and an MRN in an outbound email are different decisions.
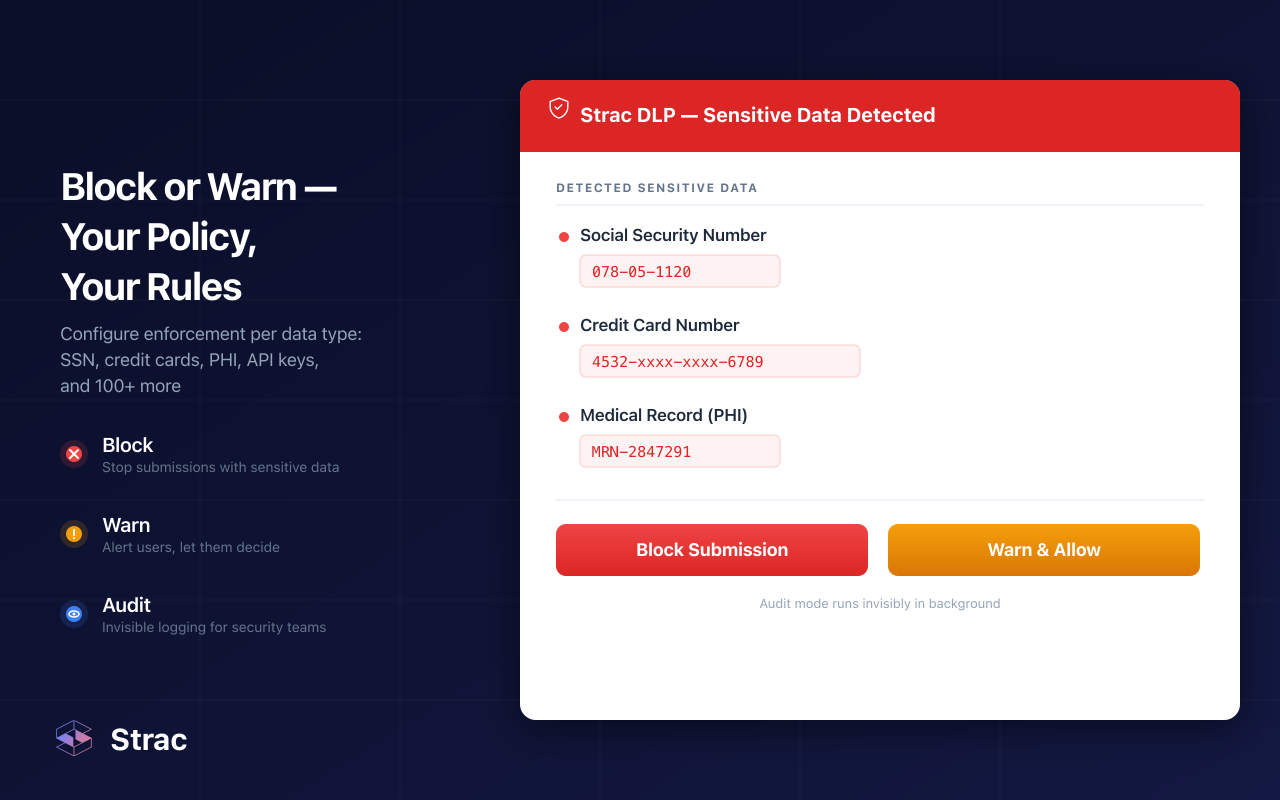
Remediate. Four actions, chosen per data type:
Redact / mask — strip the value and leave the rest usable, across SaaS, email, tickets, and docs.
Block — deny the upload, paste, or send before it completes.
Warn and coach — stop the user in the moment and require a justification.
Revoke access — remove public and external sharing on Google Drive, SharePoint, and Box.
Detection tells you PHI is there. Remediation is what keeps it from leaving.
✨ Strac: PHI Redaction Across Every Surface
Strac runs one classifier and one policy across SaaS, browser, endpoint, email, cloud storage, and databases. It handles unstructured text and scanned images alike through automated redaction with OCR, vaults originals so authorized users retain access, and logs every detection and remediation as HIPAA evidence.
Where data has to stay analytically useful, Strac tokenizes and pseudonymizes instead of destroying: consistent, realistic, joinable surrogates for testing, analytics, and AI. See data masking and pseudonymization.
In databases, the same policy runs at the column — mask, tokenize, or redact PHI in any relational or NoSQL store, including Postgres data masking. For programmatic use, the Strac API redacts PHI in your own pipelines.
PHI Redaction Readiness Checklist
If you cannot tick all eight, PHI is leaving somewhere you are not looking. The fastest way to find out which one is failing is a healthcare data security review against your actual surfaces, not your policy document.
PHI does not stay in the systems built to hold it. It ends up in tickets, threads, inboxes, and shared folders, and that is where redaction has to run. Detect it wherever it lands — including inside images — remediate it in real time, and vault the originals so care and analytics keep working. Book a demo to see Strac redact PHI across every surface your organization touches.
No. De-identification is the HIPAA standard — Safe Harbor or Expert Determination. Redaction is one of the mechanisms that gets you there, alongside masking, tokenization, and pseudonymization. See HIPAA de-identification.
Doesn't our EHR or Microsoft Purview already handle this?
They govern the systems they own. PHI leaks through the surfaces around them — support tickets, chat threads, email attachments, shared Drive folders — where those tools have no visibility and no enforcement point.
Will redaction break our support workflows and analytics?
No. Redaction leaves the record readable and pseudonymization keeps analytics joinable, so agents keep resolving tickets and analysts keep running queries while the identifiers stay protected.
Can detection catch every PHI element?
Not perfectly — no classifier is. That is why detection pairs with vaulting, revocation, and a logged audit trail: a miss is recoverable and provable, not silent.
What actually counts as PHI?
The 18 HIPAA identifiers — names, geographic subdivisions, dates tied to an individual, MRNs, health plan and account numbers, biometric identifiers, and full-face images among them. Anything that ties health data to a person.
Discover & Protect Data on SaaS, AI, MCP, Endpoints & Cloud
Strac provides end-to-end data loss prevention for all SaaS and Cloud apps. Integrate in under 10 minutes and experience the benefits of live DLP scanning, live redaction, and a fortified SaaS environment.